| Google Graphs - Detail |
|---|
|
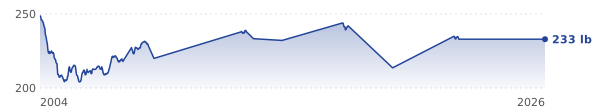
So here is a little more detail on how I did the weight graph for the footer of the blog. At Google Code They describe the API for generating a .png image of a graph. This is done by sending a request with the proper parameters in the url. the url I'm using is:
"http://chart.apis.google.com/chart?cht=lc&chxt=x,y&chxl=0:"
{ A bunch of dates here }
"1:|185|200|250|275&
chd=t:{ A bunch of weights here }&
chds=185,275&
chs=600x100&
chco=224499&
chm=B,dcdcdc,0,0,0&
chtt=Weight+Graph"
Easy as pie right? The url is a bit cumbersome but in short this is what it brakes down to:
Now where to get the data from? Well I use the blosxom blog engine for my blog. It uses a simple text file for each entry. For each daily entry I add my weight to the top. In fact I have written an emacs mode just for blogging that asks my weight and auto populates that info for me when I start the entry. So that makes grep an excellent tool for pulling out the data in those files. Originally I considered perl but that seemed a bit heavy handed. So to pull the data form the text files I used the following grep command
grep -o -P "[w|W]eight:?.?[0-9]{1,3}" *.txt
That says print out the file name and any text matching the pattern specified.
The pattern says to Look for the word "weight"(case insensitive) with an optional
colon and space afterward, and at least 1 digit but up to 3. So the out put looks like this:
UPDATE: had to remove ths as it skewed the graph
Now that is starting to look like something we can work with.
So now I want to strip away just the file name and date. awk is just the thing there.
awk -F: '{print $1 "," $3}'
This tells awk that the field separator is a colon and to print out fields 1 and
3. easy poesy!
Next I want to sort the data coming out to give it a bit of order in the graph. To accomplish this I pipe through sort. Next I pipe that output to a perl script I wrote to collect the data and craft the url. so the final cron job looks like this:
#!/bin/bash
cd /home/abturet/blog/; grep -o -P "[w|W]eight:?.?[0-9]{1,3}" *.txt |awk -F: '{print $1 "," $3}' \ | sort | ./weightgraph.pl; So what is it that the perl script does???? Well, I'll tell you. But first I'll show you
#!/usr/bin/perl
use strict; use warnings; use POSIX qw(strftime); my ($url,$img_location,$dates,$weights,$weight_counter,$date_counter,@data,$date,$weight); $weight_counter = 40; $date_counter = 100; $dates .= "|"; $img_location = "/home/abturet/public_html/images/weightgraph.png"; while(<>) { ($date,$weight) = m/(.*), ?(\d+)\n/; $date= strftime "%Y-%m-%d", (localtime((stat($date))[9])); s/^\s+/$2/; if($weight_counter == 40){ $weights .= "$weight,"; $weight_counter = 0 } if($date_counter == 100){ $dates .= "$date|"; $date_counter = 0 } $weight_counter++; $date_counter++; } $dates.= "$date|"; $weights .= $weight; $weights =~ s/,$//; $url = "\"http://chart.apis.google.com/chart?cht=lc&chxt=x,y&chxl=0:".$dates. "1:|185|200|250|275&chd=t:$weights &chds=185,275&chs=600x100&chco=224499&chm=B,dcdcdc,0,0,0&chtt=Weight+Graph\""; `curl -o $img_location -s $url `; That's quite a mouthfull. What I do is as each line comes through I capture the two parts. The date and the weight. The date is actually the file name. So I call stat on the file and use the ninth element(the create date). I format that with strftime. Then I strip any white space from the weight. The next to blocks make sure I don't send too much data. The api documentation says there is a url size limit of 3600 characters so I only grab every 40th weight and every 100th date. I have initialized them to the max value so that I have the first values from 2004 in the data set. After I've handled every date in the blog I tack on the last date and width so that the full range is represented.Then I use those big strings of dates and weights to fill in the url and use curl to send the http request and save my nifty png file. Sometimes it's fun to put your documentation out there in the public view. And now that it's here I can always find it if I want to make a change. |
| comment (0) | Ari Turetzky | permanent link |